

3·
1 month agoI’m okay with the downvotes. There’s a stronger anti-AI sentiment now than even just a month ago, and on the whole I think that’s going to be a good thing.
I’m okay with the downvotes. There’s a stronger anti-AI sentiment now than even just a month ago, and on the whole I think that’s going to be a good thing.
Yes, it was released in March. One important point is that these results are based on the semi-private test set. Perhaps it’s best to wait until it is measured against the fully private test set, but that might not happen for months.
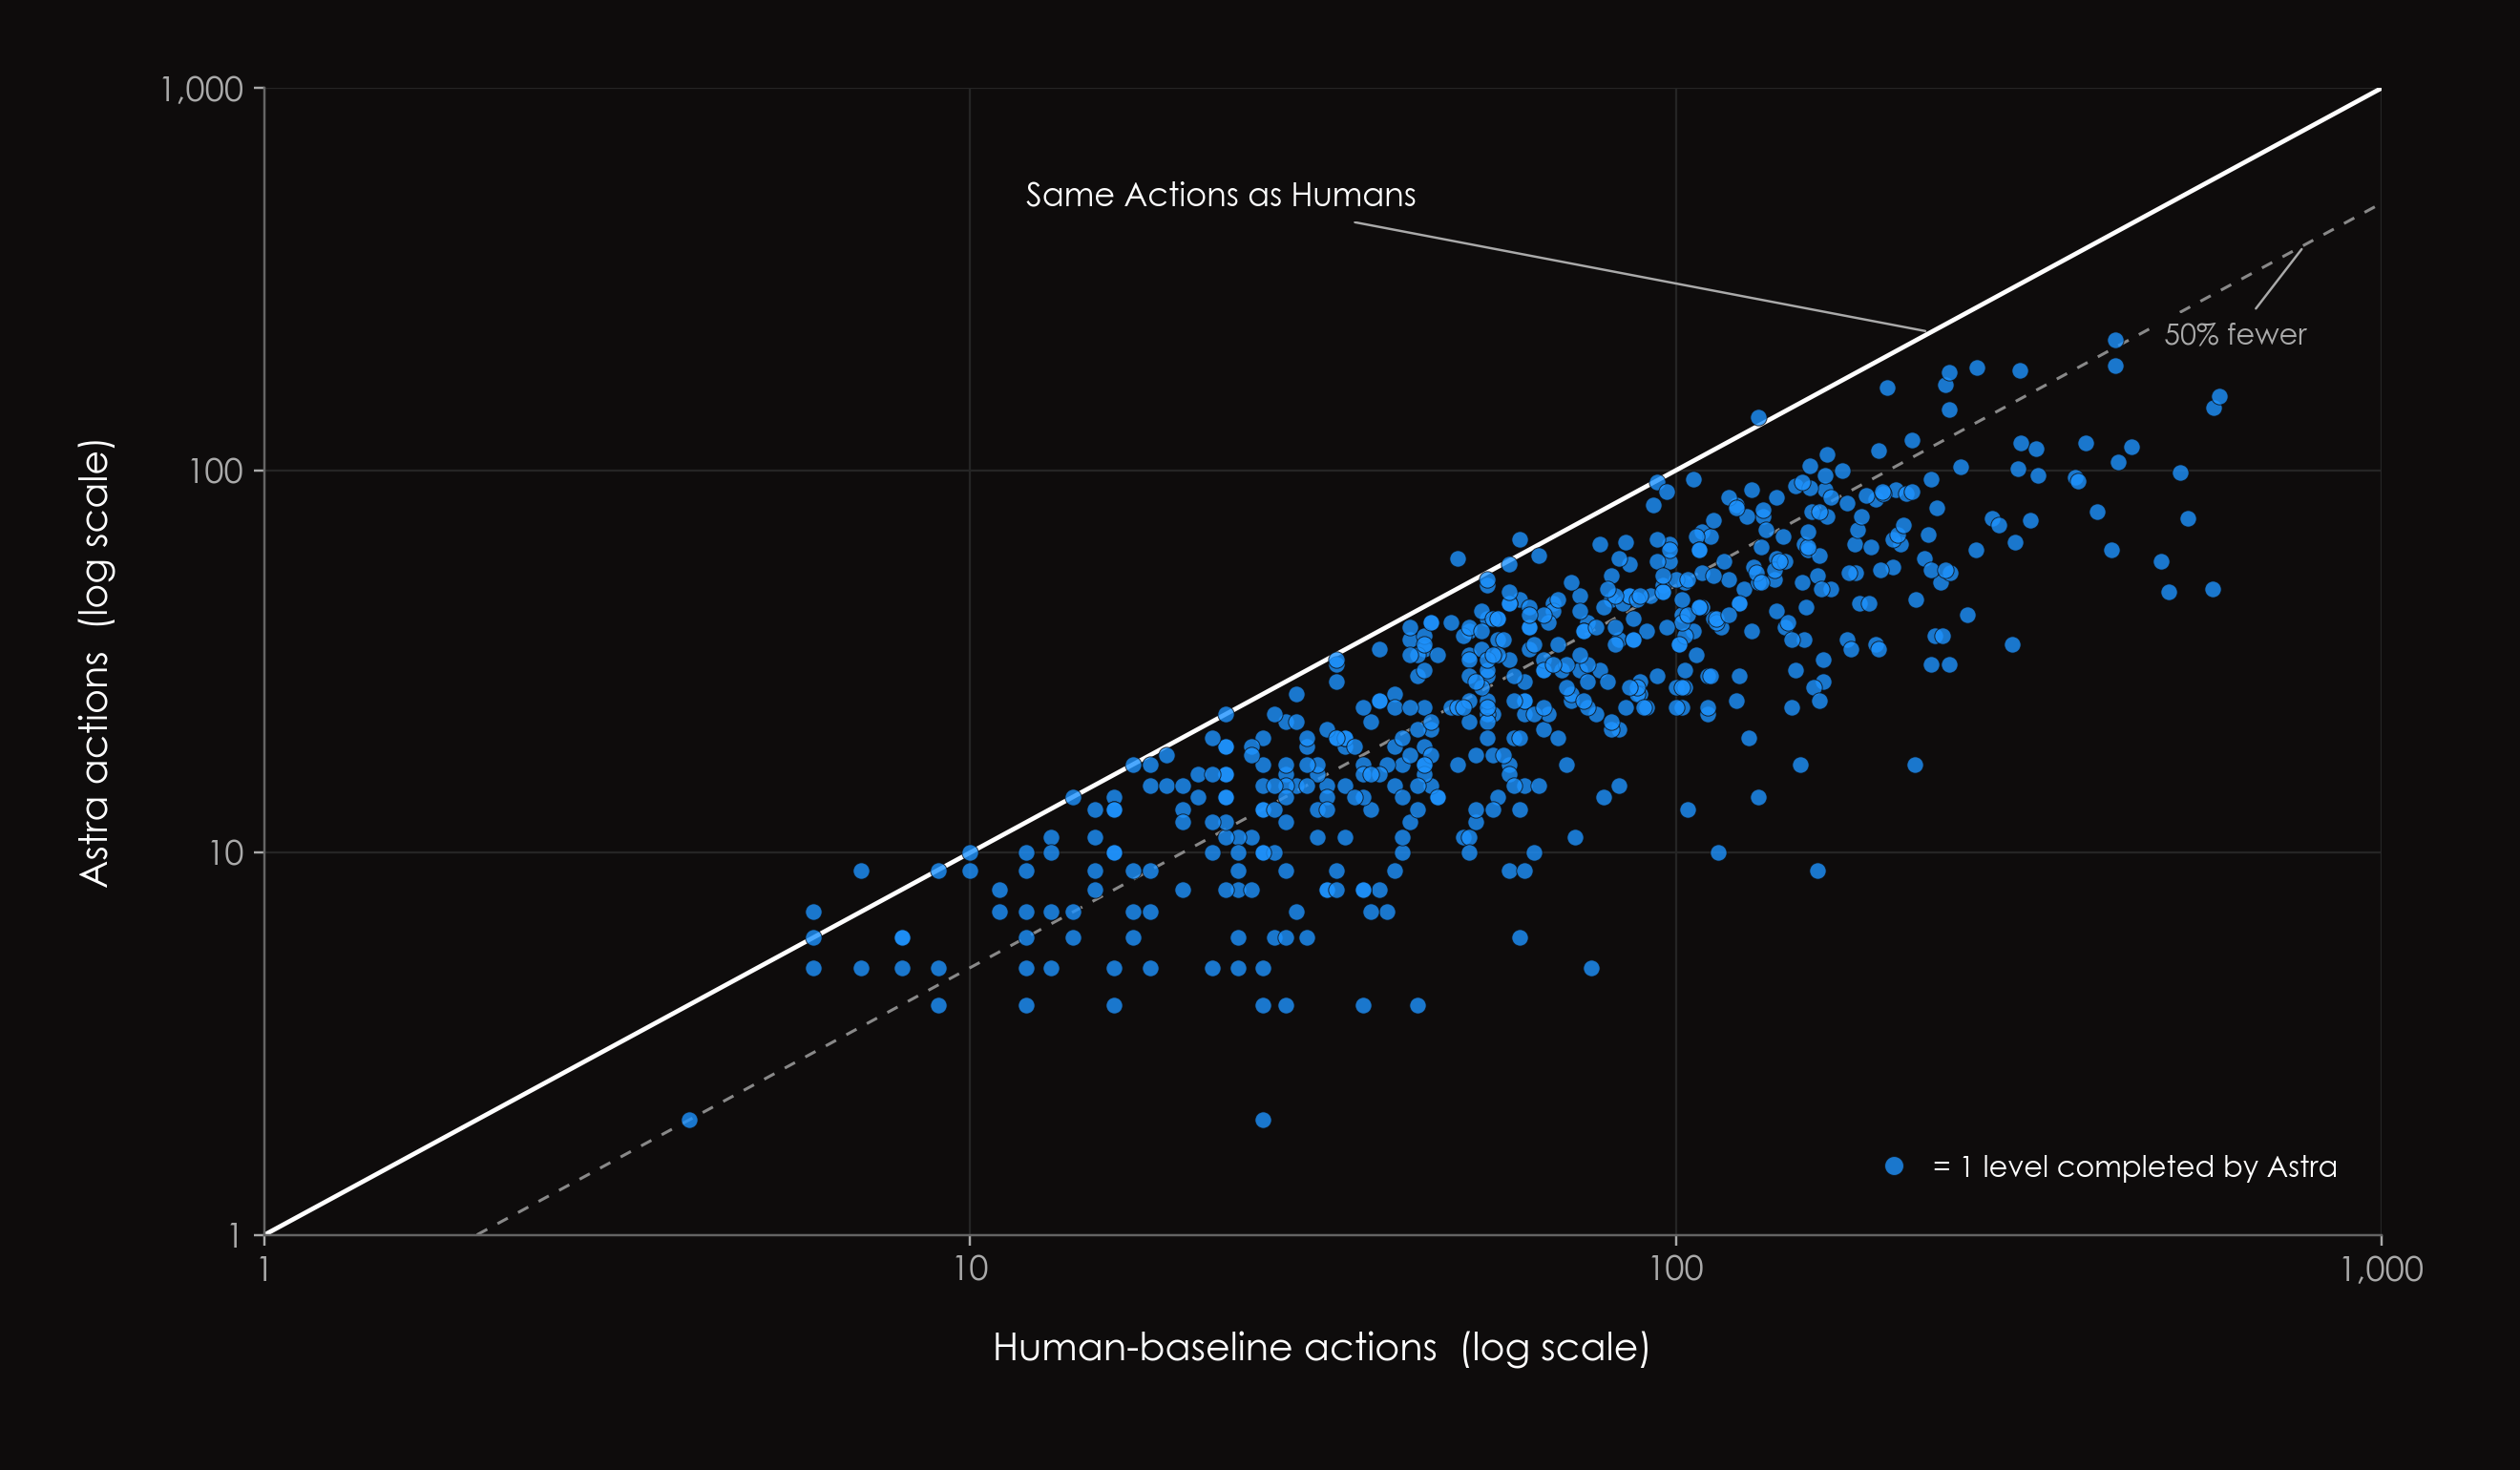
I agree with most of this. I’ve also said in the past that LLMs cannot think, and I think that’s still true for most models. The reason ARC-AGI-3 is interesting is that it was specifically designed to test reasoning, adaptability, novel problem solving, planning, memory, etc. So it was a surprise to me that Astra was able to defeat it so effectively, and that Astra invents algebras for each novel task.
But I agree we can’t trust OpenAI if these results are self-reported, and we may not be able to trust the ARC Prize Foundation fully either. Extraordinary claims require extraordinary evidence, so we need replication, transparency, and proper open science to confirm things.
I also agree with ARC Prize’s conclusion, that there are still capabilities any AI system would need to demonstrate before we can claim a full general intelligence.
I guess this is being down-voted just because it feels pro-AI. Believe me I get it, you can look at my anti-AI post history. But I think it’s important to also keep an eye out for real signals towards general intelligence, which is why I wanted to share this. I’m not celebrating it, just bringing awareness.
ARC Prize maintains multiple tracks around their benchmarks. They have “verified” leaderboards, “community” leaderboards, and they also run the ARC Prize competition.
They update the “verified” leaderboards when they test raw LLMs without sophisticated harnesses. They seem to update this sporadically and only occasionally do press releases or blog posts about new scores. For example, the latest score from Claude Opus 5 (High) is 30% at $20,000, and they didn’t post about that as far as I know. Again, this just the raw LLM without an agentic or world-model harness.
The ARC Prize competition has a harder set of criteria. Participants have to use smaller, open models with a limited compute budget, with open source code, and of course the solutions are verified by ARC Prize at the end of the competition.
The “community” leaderboards, which is what this post is about, are self-reported and not verified by ARC Prize. There are no restrictions on what model is used or limitations on compute. So naturally they aren’t going to make official news releases about those, unless they decide to verify them at some point.
The only reason I chose to post this is that the top solutions seem legitimate, with source code released, and two of them have associated papers.
It think it’s still unwise to talk about these topics in broad terms like AGI and even “intelligence”. We still have to pick the capabilities apart to have useful discussions about them. I agree these games are better tests than many benchmarks, but it’s also important to note that these solutions use a combination of well-designed deterministic harnesses, as well as LLMs. So it’s inaccurate to say that “LLMs have achieved AGI” (not sure if that’s what you were getting at). This feels like an important milestone, but we’ll have to continue to probe for failure cases in other categories of problems.
Aside from emotional intelligence, experience, embodiment, etc., these ARC-AGI-3 solutions all rely on the sandbox being a safe environment to fail. They iterate through the problem thousands of times before coming to a final solution. Many real-world human problems cannot be re-tried safely or efficiently.
I think we have to do both. Bans/restrictions to prevent immediate harms (or at least attempt to), and regulation to prevent future harms.

I kinda agree with this, except the machine learning field should bear some responsibility for begetting LLMs. In particular, they got very used to the idea of scraping the internet for huge amounts of data needed for all types of models, and paid less and less attention to how much energy their training and inference was costing versus the value the models were providing. The seeds of the problems with LLMs existed before they landed on the scene.
In case you didn’t hear, Bun was acquired by Anthropic.
If the Zig community carves out a territory of principled engineering like this, I may adopt it as my primary language and make a career out of it. Finally an island of sanity in a sea of slop.
Oof, they’re going to be in a whole lot of pain after the burst. Hopefully they can reverse course mid-way.
Bernie has good intentions, but he was AI-pilled by Geoffrey Hinton, who ironically also has good intentions. However, they are both out of touch with reality.
I’m confident enough about this that I’ve registered a prediction on Long Bets.
“No LLM-based AI will surpass 70% on the ARC-AGI-3 leaderboard, with a cost of $1000 or less, before June 2028.” - https://longbets.org/973/
I’m curious if you’d really disagree with the premise, and would you (or anyone here on Lemmy) be willing to put money down to challenge the bet? (Long Bets always donates any winnings to a registered non-profit of the winner’s choice, though it’s a $200 minimum).
Are you saying that LLMs can currently reason? How do you explain their low score on ARC-AGI-3? Do you think Transformer LLM architectures will be capable of reasoning within the next two years without some new breakthrough? What mechanism in the architecture allows them to reason?
Companies are only shooting themselves in the foot in the long term if they stop hiring junior engineers, and most of that work is not being replaced, it’s being shifted to the senior engineers who now have to babysit AIs that can’t actually do the job for any extended period of time. If you’re accepting AI code into a codebase without thorough review, then you’re also shooting yourself in the foot in the long term, because even the senior engineers won’t know the codebase after a while. If you’re doing thorough reviews in order to catch the AI bugs, well then you’re probably better off coding it yourself correctly in the first place, unless you’ve already allowed your skills to atrophy.
Do you really think AIs are reasoning when you ask them to troubleshoot technical issues? You may be lucky if the issue is already in their training data, but anything even slightly novel, and the AI is just going to bullshit an answer, and I guess you’re going to follow it blindly, since you don’t know enough to come up with an answer yourself.
Besides all that, how is open source AI going to stop junior developers from losing their jobs?
The word “intelligence” is doing a lot of heavy lifting here. LLMs lack any mechanism for true logical reasoning, and they always will by nature. This is why they fail at simple questions like “the car wash test”. It’s also why agents are expensive; They just flail around in token hungry “reasoning loops” until they happen to come across a correct solution. And it’s why Claude Opus 4.8 (High) only scores 1.5% on the ARC-AGI-3 benchmark at a cost of $10,000.
This kind of panic is just part of the hype. Wake me up when real intelligence arrives.
You almost always have nano or pico available, so it’s really unlikely that you’d get stuck with nothing but vim, unless you just didn’t know that nano existed.
Probably something like “Please bro!!! WHY DID YOU DO THIS ??!! 😭😭”

Some good debunking here: https://www.flyingpenguin.com/the-boy-that-cried-mythos-verification-is-collapsing-trust-in-anthropic/



Bless uncle Bernie, but the US is in no state to even consider this. It has installed capitalism as its king.